 Have a question? +971 56 404 0503

Tech Interviews
Trust Is the New Speed – AI, Lexis+ with Protégé and the future of legal work in the Middle East

Exclusive interview with Lara Salem, Head of Content Strategy, MENA, LexisNexis Legal & Professional
How is artificial intelligence changing the way legal professionals research information, analyze cases and prepare legal documents?
In the middle east region, one of the key challenges has always been access to legal information. Finding the right law, the latest amendment or the one judgment that changed everything took hours, sometimes days. That scarcity is ending. What is becoming scarce instead is judgement.
AI is changing legal work at three levels.
Research is moving from searching to asking. Lawyers no longer have to guess the right combination of keywords. They can pose a complex question in plain language and receive an answer linked to the sources behind it. The skill shifts from finding information to interrogating it.
Analysis is moving from single documents to synthesis. Agentic AI can take an assignment, such as comparing how a commercial agency dispute would be treated onshore in the UAE, in the DIFC and in Saudi Arabia, break it into steps, work through each one and present the results for review. Work that once filled a week of associate time can be framed, reviewed and challenged in an afternoon.
Drafting is moving from the blank page to the review. The first draft is no longer the work. The work is knowing whether that draft is right: whether the clause reflects the correct jurisdiction, whether the terminology is accurate, and whether it serves this client’s commercial reality.
In my earlier writing I described this as the rise of the “hybrid lawyer”. What has changed since is the margin for error. We can no longer say we missed a case because it was obscure, or overlooked an amendment because there was no time to look. AI has removed many of those excuses, and in doing so it has raised the standard we are held to.
AI has not made legal judgement less important. It has made it the thing that sets one lawyer apart from another.
LexisNexis recently launched Lexis+ with Protégé in the region. How does the platform help legal professionals work more efficiently, and what makes it different from general-purpose AI tools?
Early in development, our subject-matter experts told us something that became our guiding principle: an AI assistant is only as useful as the content behind its output.
General-purpose AI can tell you what the law says. That is no longer enough. Lawyers need to know how the law is applied: how a court reads a provision, what a regulator expects in practice, what a clause has to look like to stand up in a given forum. That knowledge cannot be scraped from the internet. It has to be built.
We have been building it in this region since 2010. Over those years we have put together a substantial body of Practical Guidance written by regional experts, and it sits in Lexis+ with Protégé alongside UAE federal law and other GCC laws, legislation, regulations, official gazette materials, case decisions and expert commentary. Additionally, UK content is available through the same sign-in. This is what makes the difference in the output. Protégé does not stop at the statute. It brings in the practical layer lawyers rely on every day, and every answer links back to its sources.
The region’s many layers of jurisdiction also needed particular care, especially when we built the agentic drafting. An affidavit in the UAE is not the same as an affidavit in Saudi Arabia. The differences are small, and our experts caught them. A general-purpose tool would miss them. And that is the difference.
For efficiency, the platform supports the whole cycle of legal work. It handles conversational research in plain English. Its agentic workflows break complex assignments such as due diligence, compliance reviews or legal comparisons into structured steps you can review. It drafts contracts, clauses, memos and client correspondence, drawing on a firm’s own precedents where authorised. It also analyses matter documents securely, pulling out key issues, building timelines and comparing materials. Customer data is never used to train public AI models.
What I am proudest of is how it was built. Protégé comes from a marriage between leading regional legal experts, data scientists and software engineers. Practitioners tested it, challenged it and told us where it fell short. That is what localization really means: not translating a product but teaching it how law works here.
And it is not finished. The product evolves every week, and refining its agentic skills is one of the most fascinating parts of the work. Each refinement brings it closer to the needs of our clients and of each jurisdiction we serve.
Globally, Forrester Consulting studies commissioned by LexisNexis project a 344% three-year return on investment for a composite large law firm, and 284% for a composite corporate legal department, using the platform behind Lexis+ with Protégé. We are now validating performance with regional users and will share those results as they become available.
With the growing use of AI in legal work, how can professionals ensure that the information they receive is accurate, reliable and based on trusted legal sources?
My rule is simple: never trust an answer you cannot trace.
AI can produce something that sounds convincing and is entirely wrong, and courts in this region have already had to deal with it. Earlier this year, the ADGM Courts ordered a law firm to pay wasted costs after it filed a defence relying on authorities that did not exist, generated by an AI tool and never checked. The message was clear: the failure to verify belongs to the lawyer, not the machine. The DIFC Courts have also issued guidance requiring practitioners to verify AI-generated content they rely on in proceedings.
Every AI output should face three questions. Where did this come from? Is it current? Is it the right jurisdiction? If the tool cannot answer the first, the other two do not matter.
That is why the choice of tool matters as much as the discipline of the user. Before adopting any legal AI, firms should ask hard questions. What content is the system grounded in? Is that content verified for accuracy and currency? Does every output link to its source? How was it tested, and by whom?
But even the best tool does not replace the lawyer. The lawyer is the ultimate owner of the output, and their judgement is what matters most. A provision can be quoted correctly and still be the wrong answer. It may not be the only law that applies, or the one that best fits the question at hand. Only a lawyer who understands the matter can make that call.
This is why every firm and legal department needs a clear review process for AI output, written into an AI use policy. The policy should set out who reviews what, how sources are checked, when senior sign-off is needed, and how AI use is recorded. Verification should not depend on individual habit. It should be how the firm works.
Grounding and citations reduce risk. They do not remove responsibility. So, treat AI as an assistant, not an authority. Expect speed, not certainty. Read the source and ask whether you would have reached the same conclusion yourself. AI raises the bar. It does not lower it.
What are the biggest challenges law firms in the UAE and wider GCC face when adopting AI, and how can they overcome them?
Adoption is no longer the main hurdle. Trust is. Most lawyers in the region have already tried AI. The question is whether they can rely on it for real client work, and four challenges stand in the way.
Data. Generic models are trained mostly on English-language, common-law material. Arabic legal content is far less structured and digitised. A model that has rarely seen Gulf legislation cannot reason reliably about it.
Language. Arabic is the authoritative legal language across most of the region, yet the same legal concept is not always expressed the same way from one country to the next, and a single diacritical mark can change the meaning of a provision. Legal AI here has to reflect the terminology of each jurisdiction rather than one standardised vocabulary. This was one of the hardest, and most interesting, parts of localising Protégé.
Confidentiality and data sovereignty. GCC clients are rightly protective of their information, and data protection laws such as the UAE and Saudi PDPLs set strict expectations on how personal data is handled and transferred. Many firms hesitate because they cannot answer a simple client question: where does my data go?
Culture. Partnership models, the billable hour and concerns about how juniors will learn all create reasons to wait. Too many firms are stuck in pilots that never scale.
None of these is a reason to stand still. Choose AI built for the region’s law and languages, not adapted as an afterthought. Put governance in place before you scale, not after. Start with defined, high-value use cases such as research, document review and first drafts, where results can be measured. Train every lawyer, not only the enthusiasts. And measure what changes, so the business case rests on evidence rather than excitement.
How can legal professionals use AI responsibly while protecting confidential client information and maintaining professional standards?
Every lawyer begins their career by making a promise: to act with integrity, independence and confidentiality. That oath is personal. It cannot be delegated, and it cannot be automated.
AI does not take the oath. Lawyers do.
Protecting the client starts with the choice of tool. Consumer-grade AI has no place near confidential client information. Lawyers should know where their data goes, whether it is stored, whether it is used to train models and how it is encrypted. With Lexis+ with Protégé, customer information is protected through encryption and enterprise-grade security, and it is never used to train public AI models. That should be the minimum standard for any legal AI.
Good habits matter just as much. Share only what the task requires, and redact what it does not. Be open with clients about how AI supports your work. Clients value honesty over ambiguity, and openness signals confidence, not risk.
My test is simple: use AI only in ways you would be comfortable explaining to your client, or to a judge.
What skills will lawyer and legal teams need to develop as AI becomes a bigger part of their daily work?
The most important skill of the AI era is the oldest one in the profession: knowing when something is wrong.
Verification. It will become a core discipline, taught and practised as rigorously as drafting. Lawyers will need to read sources rather than summaries, test conclusions against their own reasoning and spot the output that is plausible but missing the nuance.
Prompting. It is often misunderstood. Prompting is not a technical trick. It is structured legal reasoning. A good prompt sets out the jurisdiction, the facts, the question, the format and the standard expected, which is exactly how a good partner briefs a junior.
Supervision. Agentic AI breaks tasks into steps and works through them. The lawyer’s role becomes scoping the task, checking each stage and deciding what reaches the client. Think of it as managing a very fast junior who never sleeps and does not always say “I’m not sure”.
AI literacy. Lawyers need to understand how these systems work, where they fail and what to ask a vendor before trusting one.
The human skills. Commercial judgement, negotiation, empathy and the ability to explain complex advice clearly will matter more, not less. In the Middle East, where relationships and trust carry great weight, these are what clients will pay for.
There is also an uncomfortable question the profession has to answer: if AI produces the first draft, how do juniors learn? I believe the answer is to redesign training, not to slow down technology. Juniors can learn by critiquing AI output, tracing its sources and explaining why it is right or wrong. Done well, that builds judgement faster than years of formatting documents.
How do you see legal technology evolving in the Middle East over the next few years, and what role will AI play in this transformation?
The Middle East has an advantage many markets do not. Governments here are not reacting to AI; they are planning for it. The UAE National AI Strategy 2031 and Saudi Vision 2030 have made digital transformation a national priority, and in June the UAE announced a single federal authority for artificial intelligence and data. Legal technology will follow that ambition.
I see four shifts over the next few years.
From answering to acting. Today, most lawyers use AI to answer questions. Next, agentic systems will carry out multi-step work such as due diligence, regulatory monitoring and contract review, with the lawyer supervising and approving each stage.
From global to local. Localisation will become the price of entry. Firms will expect AI that understands the region’s mix of civil law, common-law free zones and Sharia principles, and that works natively in Arabic rather than through a translation layer.
From experimentation to governance. Regulation is emerging through courts, free zones and data protection law rather than a single AI statute. Governance will become a competitive advantage, because clients will choose firms that can show how their AI-assisted work is controlled and verified.
From hours to value. As routine work accelerates, pricing will change. LexisNexis research in the UK found that 55% of lawyers now expect firms to change how they bill because of AI. The same conversation is beginning here.
AI will be the engine of this transformation, but trusted content will be its fuel. The firms that lead will not necessarily be the ones that adopt AI first. They will be the ones whose clients trust their AI-assisted work the most.
For us at LexisNexis, after 16 years in the region, the launch of Lexis+ with Protégé is not a finish line. It is a starting point. The journey is only beginning, and it will be guided by three principles that have always defined good legal work: trust, accountability and transparency. They are not new. They are simply more important than ever.
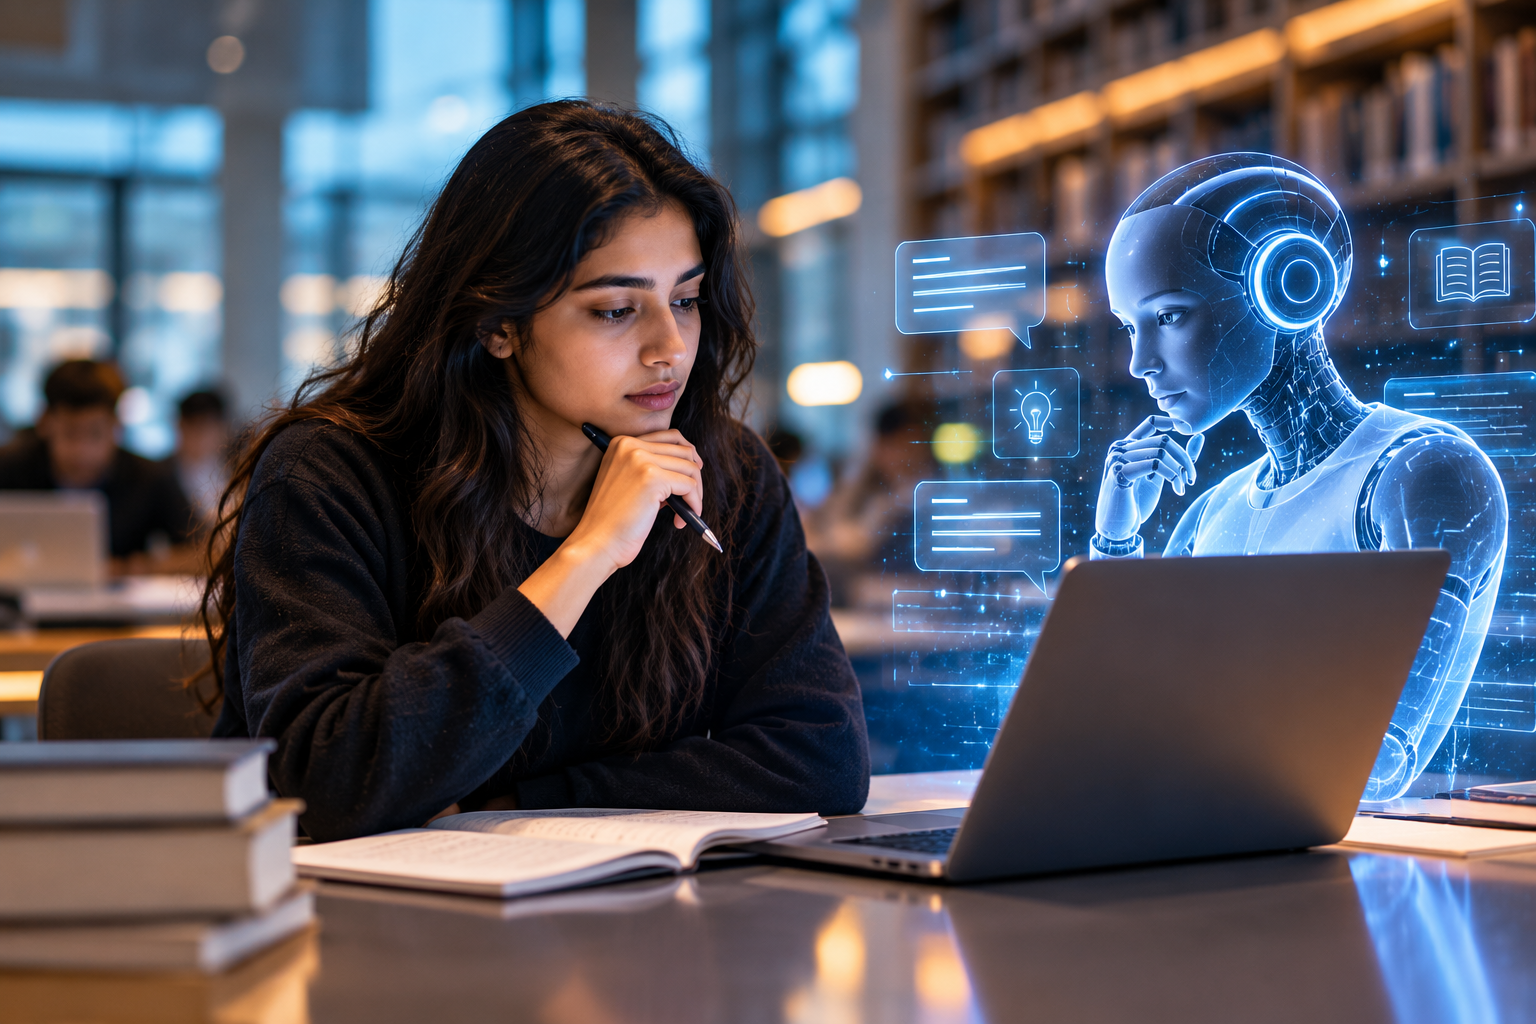
As artificial intelligence becomes embedded in higher education, universities face a growing challenge: ensuring that students develop independent thinking rather than simply producing polished AI-assisted work. From rethinking assessments to preserving the value of intellectual effort, the conversation is shifting towards what Turnitin calls learning integrity.
In this interview with Amal Dimashki – Regional Director, MENAT & Pakistan, Turnitin explores how institutions can balance AI adoption with critical thinking, meaningful assessment and the development of essential learning skills.
Students are becoming increasingly comfortable prompting AI, but how can universities ensure they are still developing independent reasoning and critical thinking rather than simply producing better AI-assisted answers?
Prompting is becoming an important skill, but being able to write a sophisticated prompt is not the same as being able to think critically.
AI can be a very effective learning partner. It can help students brainstorm, explore different perspectives, challenge an argument or receive feedback on something they have written. But students still need to do the cognitive heavy lifting. If they simply prompt AI for an answer and then refine that answer until it looks better, we may improve the quality of the output without necessarily developing the student’s thinking.
This is why AI literacy needs to go beyond teaching students how to prompt. Students need to learn how to critically evaluate AI-generated content, verify information and sources, question what they are given and make their own judgments about the output. Turnitin’s guidance on responsible prompting encourages students to engage with AI iteratively and interrogate its responses rather than simply accepting what it produces.
We want students to use AI as a learning partner while remaining actively engaged in the learning process and taking ownership of the work they produce. Turnitin’s guidance to students reinforces this by encouraging them to ensure that the majority of their work remains their original thinking.
Universities therefore need to develop AI literacy alongside critical thinking and independent judgment, so that becoming better at using AI does not come at the expense of developing the skills students are there to learn.
What should a modern assessment look like if institutions want to measure a student’s actual understanding rather than just the quality of the final submitted work?
In an AI-enabled environment, assessing only the final product gives us a limited view of whether learning actually took place. A polished final submission does not necessarily tell us how the student arrived there.
This is where a process-based approach to assessment becomes increasingly important. Educators can build meaningful checkpoints into the learning journey through outlines, drafts, formative feedback, revisions and reflection. This allows them to see how the student’s thinking developed, how they responded to feedback and where they may need additional support. Turnitin’s multipart assignments, for example, are designed around structured checkpoints for guidance and reflection throughout the writing process.
At Turnitin, we refer to the broader framework behind this as learning integrity. It expands traditional academic integrity by placing greater emphasis on the integrity of the learning process and ensuring that students are doing the work necessary to learn and develop.
It brings us back to a familiar principle: “show your work.” Greater visibility into drafts, revisions and the development of ideas gives educators richer evidence of how a student approached the assignment rather than relying on a single snapshot at the end. Turnitin Clarity, for example, provides visibility into how students develop their work from ideation through to final submission.
This does not mean making every assessment more complicated. It means designing assessment around the learning objective and creating opportunities for students to demonstrate that they have developed the skills being assessed.
The final submission will continue to matter, but it can be considered alongside evidence of the learning process that produced it.
AI makes it possible to get answers, summaries and explanations almost instantly. Do you worry that this could reduce students’ ability to sustain attention, read deeply and work through difficult material without immediate assistance?
There is certainly a risk, and students themselves recognise it. Turnitin’s research found that 64% of students are concerned that the use of AI in education may be shortcutting their learning.
Learning should not become a completely frictionless process. Researching a subject, developing a point of view, articulating ideas with evidence, editing and working through something difficult all require effort, and some of that effort is where learning happens.
Turnitin refers to this through the concept of “productive struggle.” Cognitive growth and long-term retention require students to engage with difficulty rather than having every challenge immediately removed for them.
That does not mean students should struggle without support. AI can provide guidance and feedback throughout the learning process. Turnitin Clarity’s AI Assistant, for example, is designed to prompt reflection and support students throughout their writing without generating the full response for them.
As AI becomes more capable, preserving productive struggle will become increasingly important. We want students to benefit from the support AI can provide without removing the effort involved in developing knowledge and skills.
4. Looking ahead, how do you see the role of academic integrity evolving as AI becomes embedded in writing, research and learning, and what will universities need to change over the next few years?
Academic integrity will remain fundamental, but its role is expanding as AI becomes embedded in learning.
At Turnitin, we describe this evolution through learning integrity, a proactive expansion of traditional academic integrity that places greater emphasis on the integrity of the learning process. It reflects the need to understand how students are developing their work and ensure they are developing the skills their education is intended to build.
Over the next few years, universities will need to translate this into practice. AI governance needs to provide educators with clear guidance, while recognising that responsible AI use will not look the same across every subject or assessment. Turnitin’s learning integrity framework recognises a spectrum ranging from no AI in some contexts to defined AI use cases and more open use in others.
Educators will also need greater agency over how AI is introduced into teaching and assessment. Turnitin’s latest Learning Integrity Insights found that AI decision-making is moving closer to faculty and teaching and learning leaders, while educators are asking for education-specific AI that is flexible enough to reflect how they actually teach and design assignments.
Technology therefore needs to adapt to pedagogy, rather than pedagogy adapting to the technology. This is the principle behind Turnitin Clarity’s configurable AI settings, which allow educators to determine the level and type of AI support appropriate for an individual assignment.
Over the next few years, universities will need to bring these pieces together: clear AI governance, greater educator agency, assessment practices that support learning integrity, and technology designed around the needs of teaching and learning.
Exclusive interview with Anirban Mukherjee, Director of Solutions Architecture, Red Hat
Digital sovereignty is increasingly moving beyond data residency. What does genuine operational control look like for organisations that need to retain control over their data, applications and infrastructure?
Data residency answers where information sits. Operational control answers who can run, inspect, recover, and change the stack when it matters.
In practice, that means organisations can choose where workloads run – on premises, sovereign cloud, or public cloud – without rewriting applications every time. It means they can audit the software supply chain, keep recovery paths under their own governance, and decide which models, tools, and partners sit in their AI and application environments.
For many MENA enterprises and public-sector bodies, the test is simple: can you keep serving citizens and customers if a single vendor, region, or connectivity path is constrained? Open hybrid platforms give you that room to manoeuvre because the control plane and the open source components stay portable.
As organisations continue to rely on hyperscalers, where do you see the strongest case for combining public cloud with sovereign cloud and on-premises environments?
Hyperscalers remain excellent for elasticity, global reach, and certain managed services. The strongest case for a mixed model is when data sensitivity, latency, or regulatory expectations vary across the same organisation.
We routinely see customer data, AI inference close to the data, and regulated workloads stay in sovereign or on-premises environments, while less sensitive or bursty workloads use public cloud. The point is not to reject public cloud. It is to stop treating it as the only place innovation can happen.
An open hybrid cloud approach lets MENA organisations keep one consistent platform experience across those footprints, so teams are not rebuilding skills and tooling for every environment.
Could the growing AI infrastructure requirement actually increase technology concentration, and what can organisations do to avoid creating a new form of dependency around AI platforms?
Yes, the growing AI infrastructure requirements can actually increase technology concentration, – if every AI workload is tied to one model provider, one accelerator vendor, or one proprietary stack, concentration risk simply moves up a layer.
Organisations reduce that risk by treating AI like the rest of enterprise IT: multiple models for multiple jobs, open tooling where possible, and a platform that can run across hardware and clouds. Smaller, purpose-built open models are often a better fit for specific enterprise tasks than relying on one giant external model for everything.
In the Middle East, where national AI strategies are accelerating investment, the winners will be the ones who can innovate quickly without locking the next decade of infrastructure decisions into a single vendor path.
Open hybrid cloud is often positioned as a way to balance control with access to innovation. What does a mature open hybrid cloud strategy look like in practice?
Maturity looks like consistency. Same platform, same security and policy controls, same developer experience – whether the workload sits in a national data centre, a partner sovereign cloud, or a hyperscaler.
It also looks like deliberate placement: you put each application and AI workload where it creates the best outcome for cost, performance, and governance, and you can move it when those conditions change.
For solution architects in this region, the practical question is: can the customer ship new services without creating a parallel stack every time? If the answer is yes, the hybrid strategy is working.
Vendor dependency is difficult to eliminate entirely. How should organisations assess concentration risk and maintain credible alternatives without creating unnecessary complexity?
You will always have dependencies. The goal is to make them conscious and reversible.
Assess concentration by asking: what breaks if this vendor changes pricing, exits a market, or restricts a capability? Which workloads have no second path? Where does your data or model IP become hard to extract?
Credible alternatives do not mean running five of everything. They mean open standards, portable workloads, and a clear exit or dual-run plan for the few systems that truly matter. Complexity comes from unmanaged sprawl. Discipline comes from a shared platform and clear ownership of what must stay portable.
Red Hat’s role is to help customers keep that optionality – from infrastructure through to AI – so strategic independence is designed in, not bolted on after a crisis.
Exclusive interview with Shadi Hatoum, Regional Director MEA at Tealium
The UAE is moving quickly from AI experimentation to deployment. What do you think will determine which organizations actually turn adoption into measurable business value?
The organizations that create measurable value will be those that connect AI to a clearly defined business decision, then give it the right data and operating model to support that decision.
The UAE has already built significant momentum. Boston Consulting Group found that 42% of UAE organizations qualify as AI Leaders, while 37% have reached the scaling stage of AI maturity. The next test is whether that maturity translates into sustained outcomes.
Deploying a model is not the same as changing how a business operates. AI needs trusted, consented, and real-time context around customer identity, behavior, intent, and journey stage. It also needs clear ownership, measurable objectives, and teams that understand how to use the output.
From my perspective, data readiness and organizational adoption will be the two biggest differentiators. The organizations that can put reliable context in front of AI at the moment of decision, and embed the resulting insight into daily workflows, will be best positioned to turn adoption into measurable value.
How much of the current gap between AI ambition and AI impact comes down to fragmented or outdated customer data?
A significant part of the gap comes down to data readiness, although technology alone is not the whole answer. Most organizations do not lack data. Their challenge is that the data is fragmented, difficult to interpret, or unavailable when a decision needs to be made.
Historical data provides useful depth, but AI also needs data in motion. It needs to understand what a customer is doing now, what has changed, what the customer has consented to, and whether the signal belongs to the correct individual or account.
Tealium’s Future of Customer Data research found that 88% of organizations consider real-time data important to achieving business objectives. That is important because an AI system working from yesterday’s profile may produce a technically valid recommendation that is no longer relevant.
The real opportunity is to create a trusted context layer that connects identity, behavior, consent, and intent, then makes that context available to models and decisioning systems while the customer interaction is still taking place.
Does agentic AI create a new governance problem for enterprises, particularly when agents are acting on customer data without constant human intervention?
Agentic AI does not make the principles of governance entirely new, but it raises the stakes and increases the speed at which controls need to operate. When an AI agent can move from recommendation to action, governance can no longer be treated only as a periodic policy or review exercise. It needs to operate within the data flow and decision process itself.
Enterprises need clear controls over which data an agent can access, the purpose for which it can use that data, how identity and consent are verified, which actions it is authorized to take, and when a person must review or approve the outcome.
The key question is not only whether an agent can access a piece of customer data. It is whether the agent should use that data for this customer, for this purpose, at this moment.
That requires trusted data, current consent, auditability, defined action limits, and clear escalation paths. As autonomy increases, accountability needs to become more precise, not less.
Which sectors in the Middle East do you think are furthest ahead in using real-time customer data and AI together effectively?
From my experience across the region, telecommunications and travel, hospitality, and tourism are among the most active and promising sectors because they generate frequent customer signals and have a clear need to respond in the moment.
In a recent discussion with the Chief Commercial Officer of a major telecom operator in the region, we talked about growth as filling a bucket while also stopping the leaks. Acquisition fills the top, but poor service, irrelevant engagement, and unresolved friction allow value to escape through churn. Sustainable growth requires both attracting new customers and protecting the loyal customer base already in the bucket.
This is where AI-supported decisioning can create real value. Trusted, consented, real-time behavioral data can help an operator recognize changes in usage, service issues, digital engagement, and signs of churn. The next best action may be to resolve a problem, recommend a more suitable plan, position a bespoke package at the right time, or avoid making an offer when the customer first needs support.
The objective is not to push more offers. It is to improve relevance and timing. That can support retention, strengthen loyalty, and create opportunities to grow average revenue per user, or ARPU, by responding to what the customer needs in that moment.
Travel, hospitality, and tourism have a similarly strong opportunity. The customer journey moves from inspiration and research to booking, arrival, the in-destination experience, and loyalty. Each stage creates different needs. A traveler facing disruption needs assistance, while a guest already at a destination may value a timely, personalized experience or service.
These sectors show why hyper-personalization at scale depends on trusted, consented behavioral data in motion. The value comes from giving AI initiatives the current context they need to choose the next best action for that specific moment.
At AI Everything Abu Dhabi 2026, what are the biggest changes you are seeing in the conversations enterprises are having compared with a year or two ago?
The biggest change is that enterprises are no longer asking whether they should adopt AI. They are asking how to move it into production, connect it to measurable outcomes, and govern it at scale.
A year or two ago, many conversations centered on experimentation and individual use cases. Today, the questions are more operational. Leaders want to understand how AI will work with their existing data, how agents will receive current customer context, how decisions will be controlled, and how value will be measured beyond a successful pilot.
I am also hearing much more emphasis on adoption. Organizations recognize that a model does not create value by itself. Teams need clear use cases, practical training, shared measures of success, and confidence in the data behind the recommendation.
The conversation has therefore moved from AI capability to AI readiness. That includes the quality of the data foundation, the governance around it, the ability to make decisions in real time, and the people and processes required to turn those decisions into action. For me, that is a sign that the market is becoming more mature and more focused on sustainable business impact.
Radisson Blu Hotel Dubai Deira Creek Invites Guests to Celebrate Diwali with Family, Flavour and Festive Stays
Trust Is the New Speed – AI, Lexis+ with Protégé and the future of legal work in the Middle East

Air India and Standard Chartered partner to launch travel and wealth proposition for Global Indians


-
 Trending12 months ago
OPPO A6 Pro 5G Review: Reliable Daily Driver
-

 Tech News2 years ago
Denodo Bolsters Executive Team by Hiring Christophe Culine as its Chief Revenue Officer
-
 VAR2 years ago
Microsoft Launches New Surface Copilot+ PCs for Business
-
 Automotive2 years ago
AGMC Launches the RIDDARA RD6 High Performance Fully Electric 4×4 Pickup
-
Tech Interviews3 years ago
Navigating the Cybersecurity Landscape in Hybrid Work Environments
-

 Hospitality2 years ago
Gulfood 2025 30th Edition Kicks Off Today, Setting New Benchmarks in F&B Growth and Innovation
-
 VAR10 months ago
Huawei Nova 14 Pro Review: Where Camera Excellence Meets Ecosystem Evolution
-

 Tech News1 year ago
Nothing Launches flagship Nothing Phone (3) and Headphone (1) in theme with the Iconic Museum of the Future in Dubai