 Have a question? +971 56 404 0503

Tech Features
HOW BUSINESSES CAN UNLOCK THE TRUE VALUE OF MODERN LOG MANAGEMENT

Mala Pillutla, Vice President of Sales for Log Management, Dynatrace
Without logs, it would be almost impossible to keep modern applications, cloud platforms, or customer-facing services running efficiently. Some might argue that logs are one of the most critical but least celebrated sources of truth in the digital era.
At its core, log management is about turning raw system logs — unprocessed, detailed records of a system’s activities, including server actions, user interactions, and error messages — into actionable insights. As digital systems grow in scale and complexity, logs have evolved from a backroom tool into a critical driver of reliability, performance, and security across an entire business.
From a website crashing or pages loading too slowly, to customers encountering errors or even early signs of a cyberattack, logs provide teams with a clear view of what’s happening inside their digital systems. Within an observability platform, they present the detailed “story” behind these events, helping teams move from simply knowing something is wrong to understanding why it’s happening and how to fix it before it impacts users.
Research has found that 87% of organizations claim to use logs as part of their observability solutions. That number shows how universal log usage has become. The question now is whether businesses are unlocking their full value. Collecting logs is one thing but interpreting them is another.
For too long, logs have been treated as clutter, something to store, sift, and forget. The reality is that they’re one of the clearest signals of how a business is running. Modern log management makes those signals impossible to ignore.
The limits of traditional log management
As business digital estates grow more complex, the volume of logs generated across applications, infrastructure and business services has exploded. However, more logs do not automatically mean more insight. In fact, many teams are overwhelmed by sheer volume, struggling to separate meaningful signals from background noise. This overload creates noise that makes it difficult to identify urgent issues, leaving IT and Security teams on the back foot during critical incidents and proactive response.
The problem is as much about cost as complexity. Storing and managing log telemetry without a clear purpose often leads to escalating expenses that outpace the value delivered. Traditional licensing and infrastructure models add to the problem. They often make log management feel like a financial liability than a strategic advantage.
Another common constraint is fragmentation. Logs often live across multiple tools, with different interfaces and storage models, slowing root cause analysis and complicating cross-team collaboration. In a cloud-native world where speed and scale are vital, this siloed approach is out of step with modern business needs.
Together, these shortcomings point to the need for a smarter approach—one that focuses on clarity, efficiency, and value.
Turning logs into actionable intelligence
Taking a smarter approach to log management starts with a shift in perspective. Rather than treating logs as an endless stream of technical data, leading organizations use them as a lens to understand how their digital ecosystems truly perform. The real value lies in not collecting everything but in knowing what matters and identifying which logs drive resilience, security, customer experience, or compliance, and filtering out the rest.
AI is becoming an essential part of this process. Modern techniques can detect anomalies, trace issues back to their root cause, and even trigger automated fixes. This reduces manual investigation and accelerates recovery, allowing teams to move from firefighting to foresight.
Equally important is being selective. Forward-thinking organizations decide which logs to capture, which to discard, and how to route them most effectively. This helps control costs and ensures that attention is focused on the telemetry that delivers the greatest value. When organizations find this balance, log management evolves from a tactical task to a strategic capability that strengthens both performance and resilience.
Observability and the bigger picture
Log intelligence on its own is valuable, but it is only part of the story. The next frontier is AI powered observability, uniting logs with metrics that track performance, traces that map interactions, and events that reveal key system changes. Combined in a single platform, these data types give teams a complete picture – connecting technical performance with genuine business impact and moving from a view of what happened to an understanding of why it happened and how to respond quickly.
Consider a global telecommunications provider that recently re-evaluated its log strategy. Managing more than 15TB of logs every day, stored for long periods and spread across thousands of dashboards, the team was buried in dashboards and redundant data. By consolidating logs within a broader observability framework and replacing static alerts with intelligent detection, they cut through the noise across its systems. Able to focus on the signals that mattered most, the organization improved uptime, speed, and overall resilience.
This example shows that observability delivers its greatest value when it helps teams cut through complexity. With logs feeding into a single platform, data becomes easier to interpret and act on, transforming technical insight into business intelligence.
Unlocking the true value of modern log management
Modern log management gives organizations the context they need to turn massive volumes of data into meaningful insight. Organizations that harness AI, automation, and broader observability, gain a clearer view of how their technology is supporting their goals. Enterprises can analyse faster, automate smarter, and innovate with confidence.
True modernization comes from changing how teams think about data. Now is the time to review current strategies, identify gaps, and adopt modern platforms that integrate AI, context, correlation, and smarter telemetry management practices because organizations can no longer afford to treat log management as a background IT task. The companies that thrive will be those that treat logs not as exhaust from their systems, but as evidence of how their business thinks and performs. By bringing intelligence to the data they already have, they will turn observability into a source of continuous advantage and understand their business like never before.
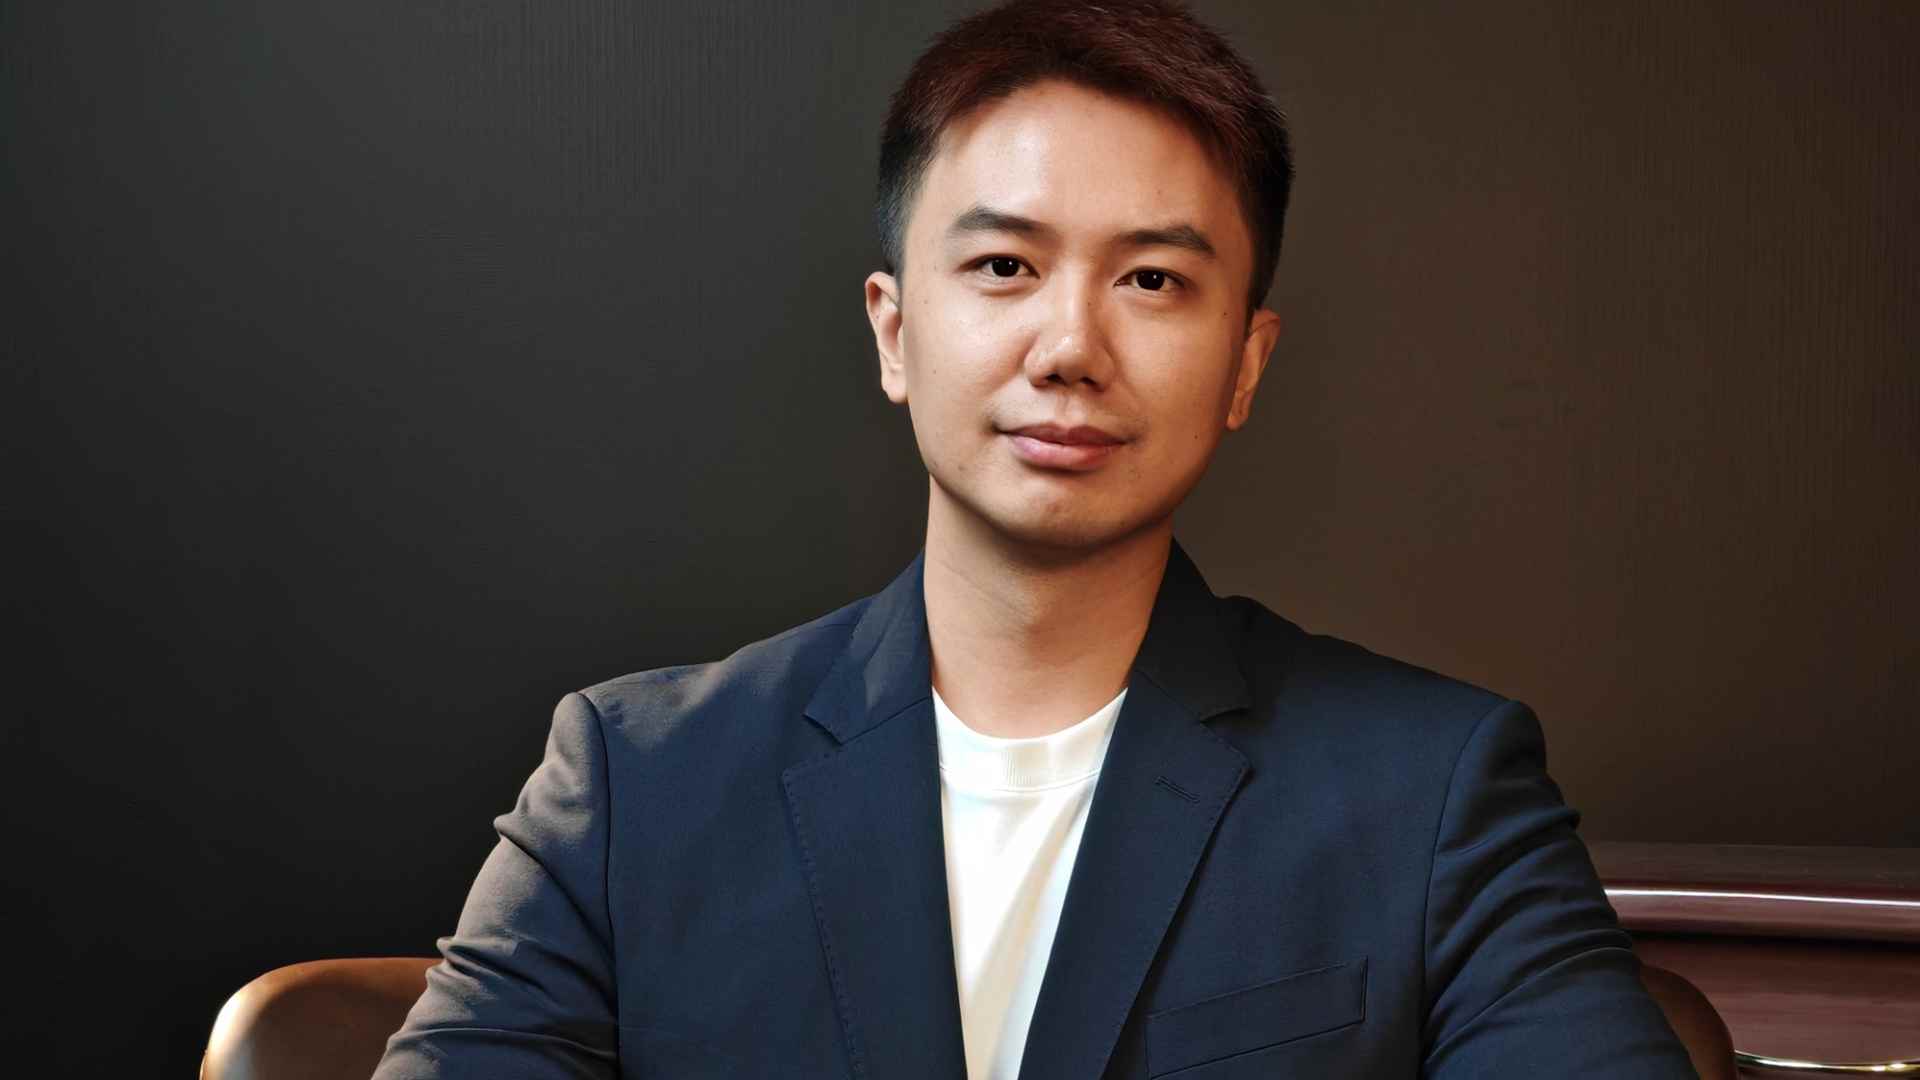
By: Debo Zhang, CEO at HONOR GCC
In the hyper-competitive consumer technology sector, the launch of a flagship device is often treated as the finish line. However, true brand leadership is forged not in the showroom, but in the months and years that follow. At HONOR, we view the point of purchase not as a conclusion, but as day one of a long-term partnership with our users.
As we aggressively push the boundaries of intelligent hardware—from integrating Agentic OS to setting new benchmarks in physical durability and battery density—we recognize that advanced specifications represent only half of the premium equation. The other half is an unyielding commitment to the customer’s lifecycle experience. If a brand fails to support its users when they need it most, the underlying technological advancements lose their meaning.
Operationalizing Community Care
Our commitment to giving back to the GCC community dictates our operational investments. We do not just build resilient devices; we build resilient support networks designed to remove the friction of long-term ownership. Our recurring monthly Service Days are not promotional events—they are structural community investments.
By deliberately absorbing operational costs—such as completely waiving labor fees for expert repairs and offering complimentary professional device cleaning and disinfection—we ensure that maintaining a premium device remains accessible. We view ongoing device care, including free system upgrades and screen film replacements, as a fundamental responsibility rather than a secondary revenue stream.
Respecting the User’s Time and Individuality
True leadership in customer service also requires a profound respect for the user’s time and individuality. Recognizing that our customers’ lives are deeply integrated with their technology, we have designed our after-sales operations to adapt to the user, rather than forcing the user to adapt to us. Offering complimentary return shipping for repairs and providing complimentary gifts when repair timelines are extended are direct measures to eliminate inconvenience.
Furthermore, we understand that a smart device is a highly personal extension of the user. Incorporating free laser engraving and custom art back films into our regular service offerings transforms a standard maintenance visit into an opportunity for users to refresh and personalize their technology.
As the Middle East accelerates its digital transformation, consumers are demanding more than just innovation; they demand reliability, accountability, and respect. HONOR’s rapid growth across the region proves a fundamental business truth: when a technology brand prioritizes post-purchase empowerment and community care over short-term transactional gains, sustainable market leadership naturally follows.
By Dr Chafic Chaya, Regional Manager, Public Policy and Government Affairs, Middle East, RIPE NCC
A business launching an artificial intelligence service rarely thinks about Internet routing. A company moving its applications to the cloud does not normally ask whether its country has deployed IPv6. And when consumers make a digital payment, stream content or access an online government service, they certainly do not think about where networks exchange traffic. They notice these things mainly when something fails.
For many years, discussions around digital infrastructure focused primarily on coverage and speed. Connecting more people and businesses, expanding fibre networks and increasing mobile broadband capacity were natural priorities. Those objectives remain important, but they are no longer sufficient.
As economies become increasingly dependent on cloud computing, artificial intelligence, digital financial services, connected industries and online government services, another question is becoming just as important: can the Internet infrastructure underneath these services scale securely and remain resilient when disruption occurs?
The next phase of digital competitiveness will therefore require us to look beyond bandwidth.
From connectivity to capability
The Internet is becoming the operating environment for entire economies. Factories depend on connected systems. Financial institutions depend on real-time transactions. Governments deliver essential services digitally. Businesses increasingly rely on cloud platforms located across different networks and jurisdictions. Artificial intelligence adds another layer of demand through large-scale data processing, distributed computing and machine-generated traffic.
Connectivity is moving beyond simple availability toward quality, reliability, affordability and resilience. This shift matters because digital innovation can only scale when the underlying infrastructure scales with it.
A country may have excellent broadband coverage, but businesses will still face limitations if networks cannot exchange traffic efficiently, if addressing resources constrain future growth, if routing is vulnerable to errors or attacks or if international connectivity depends on too few pathways.
This is why digital infrastructure needs to be understood as an ecosystem rather than simply as a collection of telecom networks.
Telecom operators are essential, but no network operates alone
Telecom operators remain central to this ecosystem. They make substantial investments in fibre, mobile networks, backbone infrastructure and international capacity. Continuing those investments is essential as traffic grows and businesses demand faster and more reliable services.
But the Internet is fundamentally a network of networks. Its resilience depends not only on individual operators, but also on how networks interconnect with one another and how effectively the wider technical ecosystem functions.
Internet Exchange Points allow networks to exchange traffic locally, while data centres bring content and computing resources closer to users. Submarine cables and terrestrial routes provide international connectivity. The Domain Name System enables users to find services, and Internet Protocol addresses allow billions of devices and services to communicate. Routing systems determine how information travels between networks. Weakness in any of these layers can affect the services built above them.
This is an important distinction. Building a resilient digital economy cannot be the responsibility of telecom operators alone. It requires cooperation between network operators, Internet service providers, data centres, cloud platforms, governments, regulators and the technical community.
The invisible foundations of scalability
Some of the most important investments in the Internet receive relatively little public attention.
The Internet Protocol version 6 (IPv6) is one example. IPv6 is the latest version of the Internet Protocol. As the supply of IPv4 addresses has long been exhausted at the global level, IPv6 provides the much larger pool of Internet addresses needed for the Internet to continue expanding and for new digital services and technologies to grow, while reducing dependence on increasingly complex mechanisms used to extend the life of IPv4. For businesses, governments and operators planning for millions of additional connected devices, cloud workloads and digital services, IPv6 should increasingly be considered basic infrastructure for future growth rather than an optional technical upgrade.
Another example is routing security. Every day, networks around the world exchange information about how Internet traffic should reach its destination. Mistakes or malicious announcements can redirect traffic or make services unreachable. Resource Public Key Infrastructure (RPKI) provides a mechanism that helps network operators verify whether a network is authorised to announce particular Internet address resources.
Local interconnection is equally important. When two networks operating in the same market can exchange traffic locally through efficient interconnection and Internet Exchange Points, data may no longer need to travel thousands of kilometres through another country and a different jurisdiction before returning to nearby users. The result is lower latency, greater efficiency and improved resilience.
Internet measurement completes the picture. Policymakers and operators need reliable data to understand how traffic flows, where connectivity is concentrated, where dependencies exist and how networks react during disruptions. You cannot strengthen what you cannot see.
Resilience has a cost, but so does fragility
One of the harder questions is economic. Network redundancy costs money, as do alternative international routes. Maintaining multiple upstream connections, deploying security measures, training engineers and continuously upgrading infrastructure all require investment.
In competitive markets, operators understandably need to balance these investments against commercial realities. The solution, however, cannot simply be to minimise infrastructure costs.
Digital dependency changes the calculation. When banking, healthcare, government platforms, logistics, cloud services and business operations depend on continuous connectivity, the economic impact of prolonged disruption can quickly outweigh the cost of building greater resilience.
Failures across interconnected digital systems can cascade into other sectors. For governments and businesses, resilience should therefore increasingly be treated as an investment characteristic, not simply as an emergency response.
The objective is not to eliminate every possible failure, as no network can guarantee that. Instead, the goal is to avoid unnecessary concentration, introduce diversity wherever practical, continuously improve security and ensure that systems can recover quickly.
The Middle East is moving from adoption to infrastructure maturity
Saudi Arabia and the United Arab Emirates provide a useful example. The lesson is that Progress tends to occur when policy attention, technical capacity building and implementation by network operators reinforce one another. Infrastructure transformation is rarely achieved through regulation alone, nor through technology alone. It requires sustained cooperation between policymakers and the people who actually operate networks.
The race to build AI capacity is attracting billions of dollars in investment across our region and around the world. But compute without connectivity cannot deliver value. Connectivity without resilience cannot guarantee continuity. And infrastructure without cooperation cannot scale indefinitely. The strongest digital economies will therefore not simply be those with the most infrastructure. They will be those with Internet ecosystems that are open, interconnected, secure, scalable and resilient enough to support whatever comes next
Kayvan Karim, Programme Director of MSc Software Engineering, School of Mathematical and Computer Sciences, Heriot-Watt University Dubai
For the past few years, the AI infrastructure race has largely been measured in scale: more GPUs, larger data centres and greater power capacity. That expansion is continuing, but the economics are beginning to change. Competitive advantage may increasingly depend not only on securing additional power, but on extracting more useful AI work from the power already available. Part of the reason is a change like AI demand. We are moving from relatively simple prompt-and-response systems towards agents that can reason across multiple steps, call tools, inspect results, revise plans and continue working autonomously. Anthropic’s latest Economic Index notes that Claude usage is increasingly shifting towards long-running agentic tasks and that more computationally intensive conversations tend to be associated with higher-value outputs.
This transition could have significant implications for infrastructure demand. A chatbot might generate one answer to one prompt. An agent performing a software-development, research or business task may invoke a model dozens of times, maintain a large context, call external tools and generate many intermediate reasoning steps before producing an outcome. Demand may therefore grow in two ways: more people using AI and more inference, model calls, and tokens processed for each task. Major AI laboratories are already working on this efficiency problem. OpenAI says one of its primary inference objectives is to serve more tokens from the same hardware, using techniques including scheduling, caching, kernel optimisation and improved model implementation. It also describes GPT-5.6 as being trained to accomplish more work per token. Google DeepMind is pursuing a similar direction: its Gemini 3.6 Flash was designed for scaled agentic workloads and uses fewer output tokens than its predecessor on several evaluations. In contrast, its recent agentic video system reduced token consumption by up to 88% for that workload.
Other approaches address efficiency at the model architecture level. DeepSeek-V3, for example, uses a Mixture-of-Experts design with 671 billion total parameters but activates 37 billion per token, so only part of the network is used for each computation. Meta has similarly worked on inference efficiency through grouped-query attention and more efficient tokenisation; the Llama 3 tokeniser was reported to require up to 15% fewer tokens than Llama 2 for equivalent text. Taken together, these approaches show that model capability is increasingly being developed alongside the cost of delivering it.
Model-level efficiency, however, is unlikely to remove the infrastructure constraint on its own. Global data-centre electricity consumption was approximately 415 TWh in 2024, according to the International Energy Agency, and its base case projects this to reach around 945 TWh by 2030. AI is expected to drive most of that growth. Efficiency is therefore improving while aggregate demand continues to rise. One reason is the Jevons, or rebound, effect: efficiency improvements reduce the resources required for each unit of work, but lower costs can also encourage greater overall use. If agents become much cheaper to operate, organisations may respond by deploying more of them, running them for longer, or applying them to tasks that were previously uneconomic. Efficiency can reduce the compute required for an individual task while still increasing total demand.
That increased demand meets infrastructure that cannot expand as quickly. Models and software can improve quickly, but grids, substations, transformers and power-generation infrastructure usually have much longer development cycles. The IEA notes that while a data centre can sometimes be developed within two or three years, the broader energy infrastructure required to support it often involves longer planning and construction periods. Where grid capacity is constrained, each available megawatt becomes a more valuable production resource. The amount of power available remains important, but so does the amount of useful computation that can be produced within that power envelope.
That changes how we should understand capacity. Improvements in accelerator performance, model architecture, workload scheduling, caching, utilisation and inference software can increase computational output without increasing a site’s electrical connection. OpenAI’s recently reported Jalapeño inference hardware illustrates the direction of travel: the company says the chip can deliver more AI work per unit of power while increasing throughput and reducing latency. Efficiency can therefore act as a form of virtual capacity. If two operators each control 100 MW, but one can consistently deliver substantially more useful AI work within that power envelope, their nominal capacity may be identical while their productive capacity is not.
The same constraint applies to physical space and cooling. AI systems are concentrating more computational power into individual racks, increasing both power density and heat output. Packing more accelerators into the same building only creates useful capacity if the electrical and thermal infrastructure can support them. This is one reason liquid cooling is moving from a specialist technology towards a more central part of AI data-centre design. Microsoft, for example, has introduced a closed-loop chip-level cooling architecture that it says eliminates evaporative water consumption for cooling and could avoid more than 125 million litres of water annually per data centre. The example also shows why power, cooling, water use and rack density cannot be treated independently.
The same shift creates a measurement problem. Power Usage Effectiveness, or PUE, has been valuable for showing how much facility energy is required beyond the electricity IT equipment consumes. It does not, however, measure whether that IT equipment is producing useful work efficiently. Uptime Institute’s 2025 survey placed average PUE at around 1.54 and noted that the headline industry figure had changed little for six years. Uptime has consequently argued for productivity measures that relate computational work to energy consumption. For AI inference, tokens per kilowatt-hour might offer one operational measure. Still, even that is incomplete: an efficient model that solves a task in 1,000 tokens may be more valuable than one generating 10,000. A more useful long-term measure may therefore be useful AI work per unit of energy, water and infrastructure.
Capacity will remain essential. The AI industry will continue to build larger data centres, secure new power supplies and deploy large quantities of computing hardware. As agentic systems create more persistent inference demand and physical resources become harder to expand, however, efficiency may increasingly determine the productive value of that capacity. Operators that can support more useful computation within the same power, cooling, water, and space constraints can accommodate more workloads without waiting for equivalent growth in physical infrastructure.
For AI infrastructure, installed megawatts will remain a headline measure. The more consequential measure may increasingly be how much useful AI work those megawatts can support.

Dubai Longevity Authority Could Accelerate Shift Towards Wellness-Led Homes

TiE Women MENA Crowns Five Regional Winners Ahead of GITEX Global Final

Beyond the camera: Why video surveillance is becoming a business intelligence tool


-
News11 years ago
SENDQUICK (TALARIAX) INTRODUCES SQOOPE – THE BREAKTHROUGH IN MOBILE MESSAGING
-
 Trending11 months ago
OPPO A6 Pro 5G Review: Reliable Daily Driver
-

 Tech News2 years ago
Denodo Bolsters Executive Team by Hiring Christophe Culine as its Chief Revenue Officer
-
 VAR1 year ago
Microsoft Launches New Surface Copilot+ PCs for Business
-
 Automotive2 years ago
AGMC Launches the RIDDARA RD6 High Performance Fully Electric 4×4 Pickup
-
Tech Interviews3 years ago
Navigating the Cybersecurity Landscape in Hybrid Work Environments
-
 Tech News2 years ago
Toshiba Announces MG10-D Series of Enterprise HDDs with Capacities up to 10TB
-

 Tech News1 year ago
Nothing Launches flagship Nothing Phone (3) and Headphone (1) in theme with the Iconic Museum of the Future in Dubai