 Have a question? +971 56 404 0503

Tech Features
THE STRATEGIC PARADOX: HOW FRONTIER TECHNOLOGIES BOTH CREATE AND SOLVE GEOPOLITICAL RISK

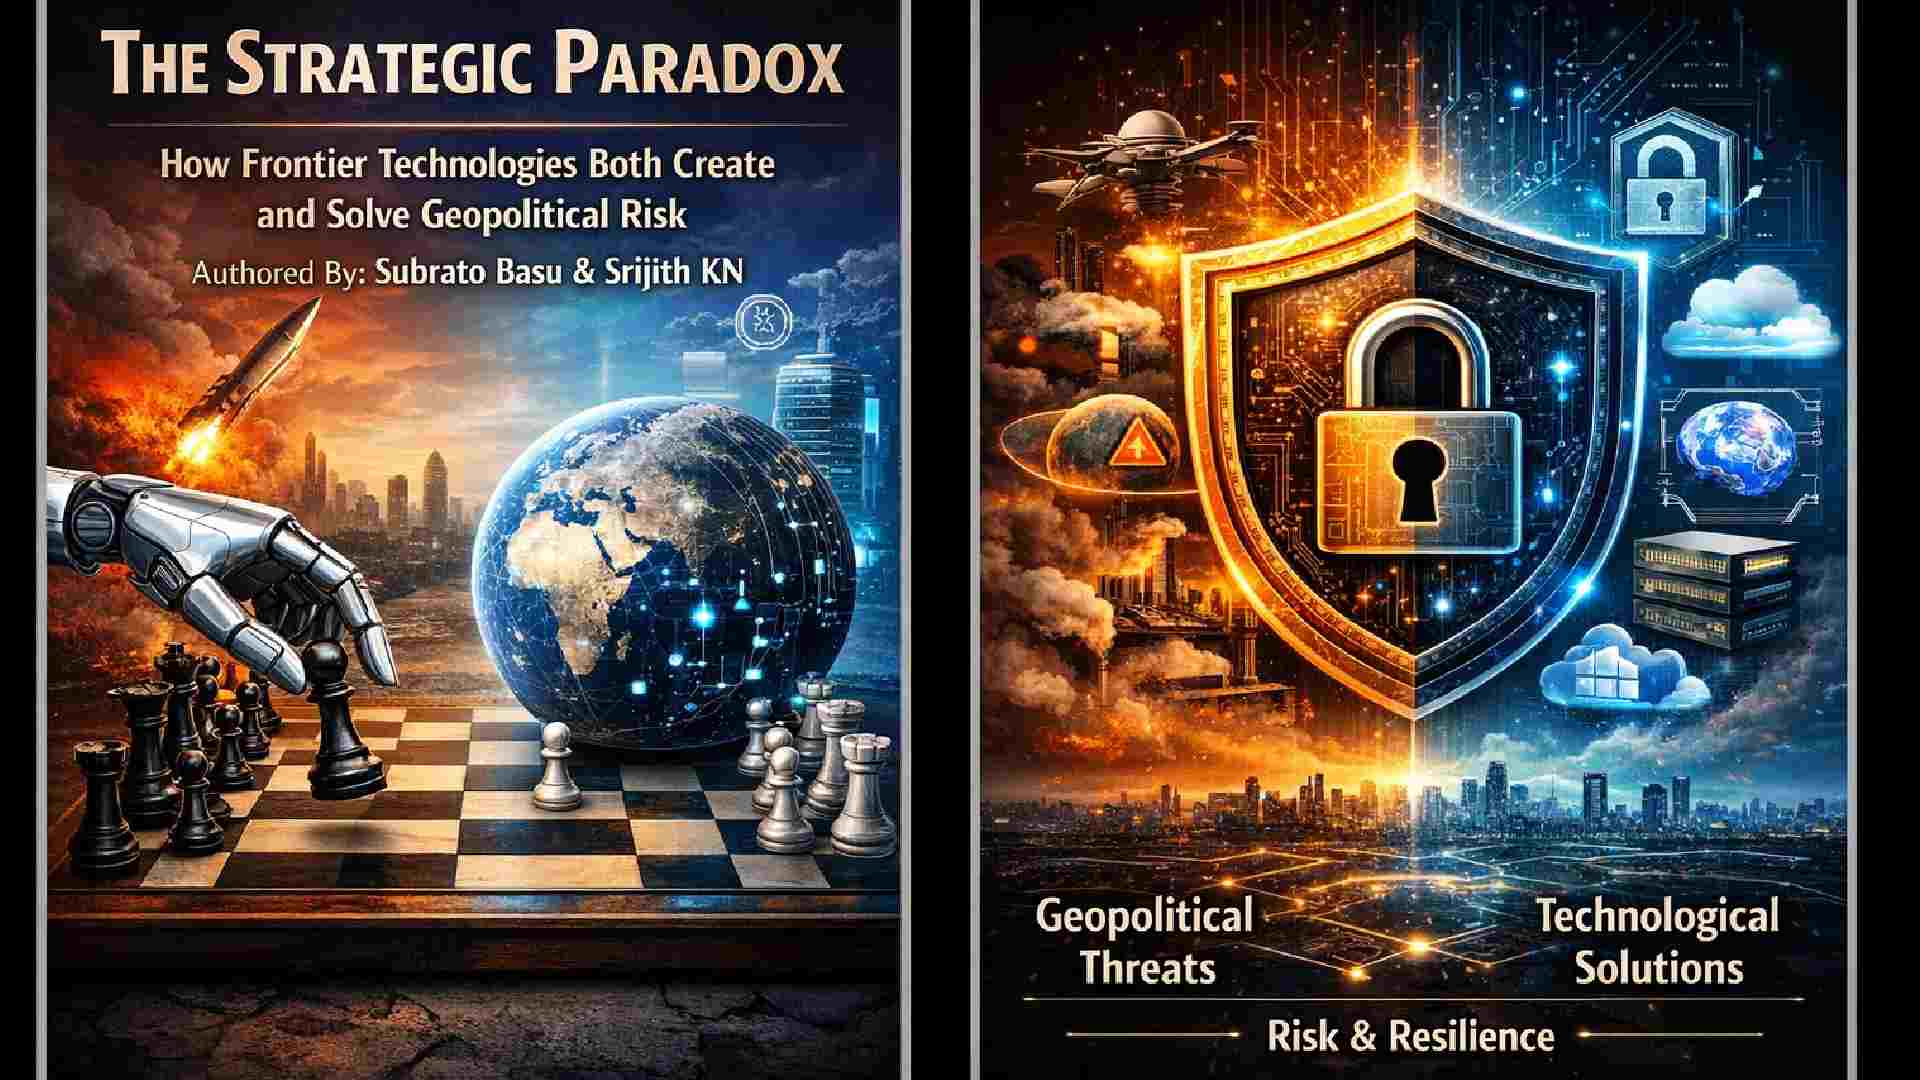
EDITORIAL NOTE: This article is a jointly commissioned work of original analysis, co-authored by Subrato Basu and Srijith KN, and published by Integrator Media as part of its Technology Leadership Series. It does not constitute legal, regulatory, investment, or security advice, and does not represent the official policy position of Integrator Media, Oxford50, or The Executive Board beyond the views expressed herein. No specific government, organisation, or individual is alleged to have engaged in any unlawful activity. Published March 2026.
If geopolitical volatility has become a structural input into enterprise technology strategy, the next question for boards and technology leaders is unavoidable: how should organisations respond?
The answer lies in a paradox that receives far less attention than it deserves. The frontier technologies most exposed to geopolitical disruption, artificial intelligence, sovereign cloud infrastructure, quantum-resilient cryptography, and agentic automation, are simultaneously the most powerful tools available for building organisational resilience against that disruption. Leaders who focus exclusively on the exposure side of this equation miss the more strategically consequential point.
Consider artificial intelligence. AI deployments built on infrastructure subject to extended regulatory jurisdiction carry real compliance exposure, as described above. Yet AI is also the most powerful accelerant available for threat detection, compliance monitoring, scenario modelling, and operational automation, precisely the capabilities that strengthen an organisation’s ability to absorb and recover from geopolitical shocks. The organisations that will navigate this environment most effectively are not those that slow AI adoption in response to geopolitical uncertainty. They are those that architect their AI infrastructure with data sovereignty and workload portability as foundational design requirements from the outset, converting a potential liability into a structural advantage.
Sovereign cloud infrastructure, whether delivered through major hyperscaler in-country residency programmes or through emerging local and regional alternatives — provides a meaningful and structurally durable buffer against vendor-level geopolitical exposure. Organisations that made this architectural decision early, as a matter of governance principle rather than in response to a specific threat event, are today in a materially stronger position than those who deferred it.
Quantum-resilient cryptography is perhaps the most time-sensitive imperative in this landscape. Advisories from government security agencies across multiple jurisdictions indicate that adversarial state actors are running long-horizon data collection programmes, systematically harvesting encrypted data today for potential decryption as quantum computing capabilities mature. For financial services enterprises, critical infrastructure operators, and government-adjacent organisations, beginning a structured transition to post-quantum cryptographic standards is a present-day governance obligation. The window to act before exposure becomes irreversible is finite.
Agentic AI and intelligent automation reduce structural dependence on specialist talent pools that may be disrupted by geopolitically driven mobility constraints. Investment in operational automation is, simultaneously, investment in organisational resilience against workforce uncertainty.
What Well-Governed Organisations Are Doing Differently
We are deliberately wary of presenting action checklists as a substitute for genuine governance change. Checklists become compliance theatre, items filed, boxes ticked, actual posture unchanged. What follows is a description of what genuinely well-governed organisations are doing differently, drawn from patterns visible in board governance practice and publicly available reporting.
They Have Made Geopolitical Risk Structural, Not Episodic
The most consequential governance shift is a reclassification, not a new process. Well-governed organisations treat geopolitical technology risk as a standing monitored variable, with an owner, a defined monitoring cadence, and a clear escalation threshold, rather than a topic that receives board attention only when a crisis forces it onto the agenda.
In practice: the CIO and CISO present a jointly owned, geopolitically aware technology resilience posture to the board at least twice annually, with scenarios explicitly modelled and stress-tested. Geopolitical technology risk appears in the enterprise risk register as a named, measured, and actively managed exposure.
They Have Mapped Their Exposure Before Needing the Map
A geopolitical technology risk assessment that maps the organisation’s most critical technology dependencies against regulatory jurisdiction exposure, relevant cyber threat vectors, and supply chain concentration risk is not a trivial exercise. But the organisations that have completed it, and kept it current through changing conditions, hold a decisive governance advantage. They know where they are exposed. They have already made architectural decisions that reduce that exposure. They are not discovering their vulnerabilities now they are least able to address them.
They Have Built Infrastructure for Portability and Sovereignty
The infrastructure decisions that matter most in a geopolitically volatile environment are not made under crisis conditions. They are made two or three years before a crisis, when there is no immediate operational pressure to make them. Migrating sensitive and mission-critical workloads to locally hosted or sovereign cloud infrastructure, dual-qualifying strategic hardware suppliers across non-concentrated supply lines and implementing zero-trust security architecture are decisions that appear cautious or unnecessary in stable conditions. They appear prescient when conditions change. The organisations in the strongest position today are those that made these decisions as a matter of strategic principle, not reactive necessity.
They Have Tested Their Continuity Assumptions Against Realistic Scenarios
Business continuity plans that have never been tested against simultaneous, compounding geopolitical stress scenarios, vendor service disruption, connectivity constraints, talent mobility restrictions, and elevated cyber incident risk converging rather than arriving sequentially, are not fit for purpose in the current environment. The organisations we consider genuinely well-prepared have run structured tabletop exercises against these compound scenarios, found their gaps in controlled conditions, and closed them before an actual event demanded it.
| BOARD READINESS: SIX QUESTIONS TO ASK THIS WEEK Can your organisation operate critical systems for 72 hours without dependency on infrastructure subject to potential extended-jurisdiction service suspension?Do you maintain offline backups of all critical data with regularly tested, documented, and rehearsed recovery procedures?Is your incident response retainer pre-authorised, contractually current, and explicitly scoped to include geopolitically-motivated threat scenarios?Have you documented manual fallback procedures for all AI-dependent and automated workflows?Is your supply chain inventory and vendor flexibility sufficient to sustain operations through a procurement constraint window of 60–90 days?Are your key technology vendors contractually required to provide advance notice before material service changes — and have you rehearsed your internal response to receiving such notice? |
A Final Word: Preparedness Is the New Competitive Advantage
There is an argument we consistently find under-made in this space, because it tends to be buried beneath the risk and compliance framing that dominates most discussions of geopolitical technology governance. We want to make it plainly.
Organisations that embed geopolitical technology risk into their governance frameworks, that build sovereign infrastructure, harden their security posture, develop resilient local talent pipelines, and rehearse continuity scenarios against compound stress events, are not simply managing downside exposure. They are building a form of operational resilience and institutional credibility that becomes a genuine, durable competitive advantage at precisely the moments when the advantage is most valuable. When conditions deteriorate, prepared organisations keep operating. They hold the trust of customers and regulators. They are positioned to capture ground from competitors who were not ready.
The structural forces generating geopolitical volatility across the global technology landscape, the intensification of great-power competition, the normalisation of technology restrictions and counter-measures as instruments of statecraft, and the sustained deployment of cyber capabilities as tools of strategic leverage, are not resolving on any near-term horizon. For enterprises operating in or near the fault lines these forces create, a ‘wait and see’ governance posture is not a neutral position. It is a choice to carry exposure that is available to be reduced.
What this moment calls for is a board and CXO community willing to apply to geopolitical technology risk the same intellectual discipline, analytical rigour, and governance seriousness it applies to financial risk: modelling it explicitly, monitoring it continuously, stress-testing it regularly, and managing it actively rather than observing it passively. The organisations that do this work now will not merely survive the next escalation cycle. They will emerge from it operationally stronger, commercially more resilient, and holding the trust and confidence that defines long-term enterprise value.
Technology leadership has always required navigating a world more complex than the tools designed to govern it. The nature of that complexity has simply changed. The discipline required to meet it has not.
| In a fractured world, operational resilience is not a risk management outcome. It is a competitive strategy. The organisations that understand this distinction will define the next generation of technology leadership. |
| SUBRATO BASU CEO, Oxford50 | Global Managing Partner, The Executive Board Subrato Basu advises boards and senior technology leaders across industries on governance, risk, and enterprise strategy. He brings a practitioner perspective shaped by engagements across the Asia-Pacific region and beyond, with particular focus on technology governance, go-to-market strategy, and organisational resilience in complex operating environments. | SRIJITH KN Senior Editor, Integrator Media Srijith KN is Senior Editor at Integrator Media, covering enterprise technology, cybersecurity, and digital transformation across the Middle East and Asia. He brings an editorial perspective drawn from tracking technology leadership decisions across markets in periods of rapid change, and a sustained focus on how organisations translate strategic risk into governance action. |
Exclusive interview with Diego Parra, Managing Partner, Megarme
How are oil and gas companies in the GCC changing the way they inspect and maintain their equipment and infrastructure?
We see a stronger emphasis on equipment condition and the consequences of failure when operators plan inspection. Scheduled inspections remain important, alongside operating history, service conditions and the role each asset plays in the operation.
Two similar pieces of equipment may need different inspection plans because their service conditions, exposure or importance to the operation are different. A critical process line, for example, may require a different approach from a low-consequence utility line. The inspection method, coverage and timing should reflect those differences while meeting the applicable requirements.
Inspection history and equipment monitoring can help maintenance teams identify changes early enough to investigate and plan work. This is particularly useful offshore or where access depends on a shutdown, because arranging people, equipment and materials can take time.
At Megarme, we support this approach by providing condition information from the locations included in the inspection scope. Our findings help the operator and its engineering team decide what needs attention, what requires further assessment and what can be included in a planned maintenance campaign. We aim to make the findings clear enough to support those decisions.
What are the biggest challenges companies face when inspecting and maintaining offshore and onshore facilities, and how does Megarme help address them?
A practical challenge is obtaining a reliable assessment while working within the facility’s operating constraints. Access, process safety and inspection quality have to be planned together. The easiest location to reach may not be the one most likely to deteriorate.
Offshore, marine corrosion and possible fatigue at connections subject to repeated loading need attention. Weather windows, restricted deck space and transport arrangements also affect the work. Under-deck steelwork, derricks and flare structures can be demanding, particularly when inspection must be coordinated with lifting or other activities nearby.
Onshore, congested pipe racks, hot surfaces and operating process systems can restrict access. Isolation requirements and shutdown schedules often determine when work is possible. Entry into tanks or vessels introduces additional atmospheric and rescue considerations.
We help by planning the access and technical work together. An under-deck survey may require surface preparation, thickness measurements and weld examination before the engineering team can assess the findings and approve repairs. Identifying these dependencies early helps the operator prepare the work.
Our reports need to make inspection coverage and limitations clear. Work during operation is considered only where the process conditions, risk assessment, permits and required isolations allow it.
How does rope access help Megarme carry out inspection and maintenance work in hard-to-reach areas safely and efficiently?
Rope access allows us to position a qualified technician directly at the work location, including beneath a jetty, beside an elevated pipe support or at a derrick connection. For localised inspection and repair, it can reduce the access structures, material handling and space required.
We are an IRATA Operator and Trainer member. The normal rope access arrangement uses two independently anchored lines: a working line and a safety line. An IRATA Level 3 supervisor oversees the rope access safety arrangements, including equipment checks, rope protection, communication and a rescue plan suited to the location. Team size must support both the task and a potential rescue.
Our technicians also need the qualifications and authorisations for the work being performed. Rope access competence is separate from competence in NDT, welding or coating inspection. An ultrasonic examination carried out on ropes must meet the applicable inspection requirements, including calibration, surface preparation, probe positioning and coverage.
We select the access method around the task, duration, equipment loads and rescue requirements. Depending on the work, that may involve rope access alone or a combination of access arrangements. The practical benefit is being able to reach the required locations with a method suited to the inspection or repair.
How does Megarme use non-destructive testing (NDT) to identify corrosion, cracks and other damage before they become serious problems?
We use NDT to assess remaining wall thickness and look for indications of cracking or other damage. We select the method to suit the material, expected deterioration and inspection requirements.
For pipework corrosion, ultrasonic measurements establish wall thickness at the inspected locations. If we find an unusually low reading, we verify it, promptly raise any critical concern and extend the examination as required to establish the extent of the thinning. Corrosion mapping can provide more detailed coverage where localised attack is suspected. The lowest measured thickness and size of the affected area matter, because an average can conceal a severely thinned location.
Magnetic particle testing can reveal surface and near-surface discontinuities in ferromagnetic materials, such as carbon steel. Penetrant testing can reveal discontinuities open to the surface in suitable nonporous materials. Ultrasonic testing, including phased array, and radiography can be used to examine welds for internal discontinuities. Selection depends on the expected damage, component geometry and applicable requirements; each method has limitations.
We record the component, examination location, coverage, measurements and relevant images or scan data. The findings support the responsible engineer’s decision on further assessment, monitoring or repair. Repaired welds are re-examined as required by the applicable procedure and acceptance criteria. Qualified personnel, suitable procedures and prompt reporting are essential to making the results useful.
How do extreme heat, humidity and salt exposure in the Gulf affect industrial equipment, and what can companies do to protect their assets?
In the UAE and Saudi Arabia, asset protection has to reflect the location. Offshore and coastal facilities face salt exposure and periods of high humidity alongside heat. Further inland, heat and dust become more prominent considerations. The protection system must suit both the local exposure and the equipment’s operating conditions.
We pay particular attention to pipe supports, bolted connections, undersides of structures and insulated pipework. Corrosion can develop in a small, critical area while the wider structure appears acceptable. Moisture entering through damaged insulation cladding can remain against the steel, making targeted inspection and repairs to water-entry points important.
Coating performance depends on preparation and application. Salt, dust and other contamination must be controlled to the specified cleanliness limits, with the required surface preparation and coating thickness verified. Steel temperatures in summer can exceed a product’s application limits. Cooler hours still require checks for humidity and condensation. Some specifications require the steel to remain at least 3°C above the dew point, alongside the product’s other temperature and humidity limits.
Our inspection, surface preparation, coating and repair work can help address deterioration and its causes. Metal loss needs assessment and, where required, an approved repair before protection is reinstated. Leaving a water trap or damaged insulation seal in place can expose the asset to the same problem again.
How does Megarme help oil and gas operators extend the life of their assets while maintaining safety standards?
We support asset life extension by gathering inspection evidence and carrying out approved maintenance or repairs. The starting point is understanding the condition of the equipment, the extent of any damage and its significance for continued operation.
For pipework, thickness measurements and corrosion mapping provide information for assessing metal loss. Our access capability helps reach components that would otherwise be difficult to examine or replace. The inspection scope needs to reflect the expected damage and provide the information required for the engineering assessment.
Our maintenance and repair scope can include surface preparation, coating, work on columns and piping, structural welding and composite repairs, where appropriate to the assessed condition and approved scope. Composite repairs require an engineered design approved for the specific damage and service conditions, controlled installation and the required inspection and verification. Completed work needs the specified quality records before acceptance.
Life extension also requires a plan beyond the immediate intervention. The operator needs to know what should be monitored, when further inspection is required and which operating limits apply. We contribute inspection data and execution capability. The responsible operator and engineering authority determine fitness for continued service and approve any extension of operating life.
What steps does Megarme take to protect workers when carrying out inspection and maintenance work in challenging environments?
We plan our work around a task risk assessment, competent supervision, personnel fit for the assigned work and the facility’s permit requirements. The controls must be confirmed at the worksite, and any change in scope or conditions requires reassessment.
At operating facilities, this includes verified energy isolation, atmospheric testing and monitoring as required, and controls for hazards such as hydrogen sulphide or flammable atmospheres. We seek to avoid confined-space entry where a suitable alternative exists. Where entry is necessary, the arrangements must address unsafe oxygen levels and other identified hazards, with suitable ventilation, communication and a rescue plan specific to that space.
At height, we consider the people below as well as the technicians. Tools need suitable retention and checked attachment points, with exclusion zones appropriate to the task. Heavy equipment requires its own handling and securing arrangements. Accounting for tools when work is complete helps prevent a later dropped-object hazard.
Our heat management arrangements need to reflect the site conditions, workload and protective clothing. The assessment guides acclimatisation, work and rest arrangements, hydration and access to shaded or cooled recovery areas.
We expect personnel to stop work when conditions are unsafe. Supervisors must respond to fatigue, changing weather and any condition that compromises the controls or rescue arrangements.
How are new technologies changing the way oil and gas companies inspect equipment and plan maintenance?
Technology can improve inspection coverage and the speed at which information reaches maintenance teams. Across the industry, drones can support visual surveys, robots can carry sensors across suitable surfaces, and permanent monitoring can identify changes between periodic inspections. Their suitability depends on the asset and the information required.
Encoded ultrasonic scanning is a practical example. It links measurements to their positions, allowing wall loss to be mapped and compared with later examinations when the scan locations and measurement conditions are comparable. Digital records can connect those results with the asset reference, earlier findings and repair history.
We assess a technology by the information it provides and the decision it supports. A visual image may identify an area for closer examination. Confirming wall loss or characterising a defect requires a method suited to that task. AI tools can assist with screening where their performance has been validated for the intended use, with qualified personnel reviewing the results.
Our priority is to select methods that suit the component and expected damage, and to produce clear, traceable records. We use inspection findings to plan any further examination and support the engineering assessment and approval of required repairs.
How can companies reduce maintenance costs and downtime without compromising safety or equipment reliability?
Better preparation and fewer repeat interventions can help control maintenance costs and downtime. The cost of a task includes access, mobilisation, materials, permits, isolation, production disruption and verification. These need to be considered together when comparing ways to execute the work.
Before a shutdown, available inspection findings should be used to define repair scopes, prepare materials and spare parts, agree procedures and secure the necessary personnel. Operations, engineering and maintenance teams need to resolve dependencies early. Discovering that a repair needs additional materials or approval after equipment has been shut down can put the programme under pressure.
We help by coordinating compatible activities within an access campaign. Elevated steelwork, for example, may need condition assessment, NDT, a dropped-object survey and authorised coating repairs. When safely sequenced, these activities can share access arrangements and reduce repeat mobilisation. Required approvals and inspection hold points still apply.
Prompt decisions on findings and investigation of recurring defects also help prevent delay and rework. Useful performance measures include total maintenance cost, unplanned downtime, repeat failures and closure of critical findings. Any cost-reduction plan must preserve required inspections and the maintenance and testing of safety-critical equipment.
What are the main inspection, maintenance and safety challenges you expect the GCC oil and gas industry to face over the next few years, and how is Megarme preparing for them?
We expect an important challenge to be balancing maintenance of operating assets with inspection needs during construction and commissioning. When shutdowns and project activities overlap, there can be pressure on the availability of experienced personnel and technical supervision.
Advanced NDT technicians, welding and coating inspectors, and rope access supervisors need the competence and approvals for each assignment. Our preparation includes attention to training, personnel allocation and the technical support available to site teams. Resources need to match the work being accepted.
The quality of records handed over from construction to operations is another priority. Traceable weld records, baseline thickness measurements and coating inspection results give maintenance teams a useful starting point. Consistent component identification helps later inspection results be compared with the correct earlier records.
For existing facilities, corrosion in difficult-to-access areas and beneath insulation will continue to require attention. On safety, overlapping inspection, lifting and hot work need careful coordination. Heat exposure and fatigue also need to be reflected in staffing and schedules.
We are focusing on consistent technical review, equipment readiness and clear reporting across our regional operations. Our aim is to keep the standard of execution consistent as workloads change, with appropriate supervision and follow-up on significant findings.
Tech Features
SANS Institute Strengthens Regional Cyber Readiness with AI-Focused Training at SANS Gulf Region 2026
SANS Institute, a global leader in cybersecurity training and certifications, has announced the 2026 edition of SANS Gulf Region. The event every year brings together cybersecurity professionals for an extensive program of hands-on training designed to address the Middle East’s threat landscape. Taking place from October 31 to November 26, 2026, at the Hilton Dubai Jumeirah Beach Resort, the event will feature 13 specialized courses and two NetWars tournaments. The program will cover key areas such as AI security, advanced threat detection, industrial control systems security and cyber resilience.
As Middle East enterprises advance digital transformation and adopt more AI-driven technologies, cybersecurity investment continues to grow. According to Mordor Intelligence, the regional cybersecurity market is estimated to reach USD 23.54 billion in 2026, growing at a CAGR of 14.55% through 2031. However, there are still challenges in developing the expertise needed to secure complex digital environments. PwC’s 2026 Global Digital Trust Insights: Middle East findings reveals that 53% of regional respondents identified lack of knowledge in applying AI to cyber defense as a major hurdle, highlighting the need for specialized cybersecurity training to keep pace with technological advancements.
As AI is integrated into business processes, cybersecurity expertise should go beyond traditional threat detection and response to securing AI systems themselves. For going through this shift, SANS Institute has developed the AI Security Maturity Model – Gulf Region. The framework provides a structured approach to evaluating AI security readiness, identifying gaps and prioritizing improvements across AI protection, utilization and governance. It offers a clearer path towards building stronger, more mature AI security practices, while reinforcing the need for continuous, hands-on training.
“The Middle East has seen remarkable progress in digital transformation, but the pace of adopting technologies must be matched by an equally strong investment in cybersecurity capabilities,” says Ned Baltagi, Managing Director, Middle East, Turkey and Africa at SANS Institute. “As businesses incorporate AI and interconnected systems, the challenge is ensuring that they have the specialized skills and practical experience to manage the risks that come with it. This calls for a shift from reactive skills development to continuous, forward-looking training that anticipates how threats and technologies are evolving. With SANS Gulf Region 2026, we are putting this approach into practice, focusing on the skills and real-world challenges that matter most to companies across the region.”
This year’s curriculum covers five key areas, including Cyber Defense, Offensive Operations, Industrial Control Systems, Cloud and AI Security, and Leadership. The program introduces SEC545: GenAI and LLM Application Security, a new course focused on securing generative AI applications and large language models. Also, there are major updates to LDR519: Cybersecurity Governance, Risk, and Compliance. Six courses are focusing on AI, reflecting the growing importance of understanding and managing AI-related cybersecurity risks.
Other key training areas include network monitoring and threat detection, enterprise penetration testing, security automation for red, blue and purple teams, ICS/SCADA protection, and defensible security architecture built around Zero Trust principles. Together, these courses address a broad range of technical and strategic requirements, helping to strengthen capabilities across both traditional and new cybersecurity domains.
Complementing the training program, the event will feature two NetWars Core tournaments, giving participants an interactive environment to apply their skills to simulated cybersecurity challenges. This year’s AI-forward scenarios will explore areas like prompt injection, malware reverse engineering, MFA bypass, web application security and IoT vulnerabilities. Set within a fictional organization facing compromised systems and vulnerable AI models, attendees should investigate and respond to interconnected security threats.
The event will also host a series of evening community talks. Sessions will explore cybersecurity leadership, the role of AI in learning, and modern influence operations, with contributions from SANS experts including Mark Williams and Jeff McJunkin. The courses will be available in person and through online live sessions.
Through SANS Gulf Region 2026, SANS Institute continues its commitment to strengthening cybersecurity capabilities across the region, supporting businesses in developing the technical expertise, leadership skills and practical readiness needed to protect complex digital environments.
Kayvan Karim, Programme Director of MSc Software Engineering, School of Mathematical and Computer Sciences, Heriot-Watt University Dubai
For the past few years, the AI infrastructure race has largely been measured in scale: more GPUs, larger data centres and greater power capacity. That expansion is continuing, but the economics are beginning to change. Competitive advantage may increasingly depend not only on securing additional power, but on extracting more useful AI work from the power already available. Part of the reason is a change like AI demand. We are moving from relatively simple prompt-and-response systems towards agents that can reason across multiple steps, call tools, inspect results, revise plans and continue working autonomously. Anthropic’s latest Economic Index notes that Claude usage is increasingly shifting towards long-running agentic tasks and that more computationally intensive conversations tend to be associated with higher-value outputs.
This transition could have significant implications for infrastructure demand. A chatbot might generate one answer to one prompt. An agent performing a software-development, research or business task may invoke a model dozens of times, maintain a large context, call external tools and generate many intermediate reasoning steps before producing an outcome. Demand may therefore grow in two ways: more people using AI and more inference, model calls, and tokens processed for each task. Major AI laboratories are already working on this efficiency problem. OpenAI says one of its primary inference objectives is to serve more tokens from the same hardware, using techniques including scheduling, caching, kernel optimisation and improved model implementation. It also describes GPT-5.6 as being trained to accomplish more work per token. Google DeepMind is pursuing a similar direction: its Gemini 3.6 Flash was designed for scaled agentic workloads and uses fewer output tokens than its predecessor on several evaluations. In contrast, its recent agentic video system reduced token consumption by up to 88% for that workload.
Other approaches address efficiency at the model architecture level. DeepSeek-V3, for example, uses a Mixture-of-Experts design with 671 billion total parameters but activates 37 billion per token, so only part of the network is used for each computation. Meta has similarly worked on inference efficiency through grouped-query attention and more efficient tokenisation; the Llama 3 tokeniser was reported to require up to 15% fewer tokens than Llama 2 for equivalent text. Taken together, these approaches show that model capability is increasingly being developed alongside the cost of delivering it.
Model-level efficiency, however, is unlikely to remove the infrastructure constraint on its own. Global data-centre electricity consumption was approximately 415 TWh in 2024, according to the International Energy Agency, and its base case projects this to reach around 945 TWh by 2030. AI is expected to drive most of that growth. Efficiency is therefore improving while aggregate demand continues to rise. One reason is the Jevons, or rebound, effect: efficiency improvements reduce the resources required for each unit of work, but lower costs can also encourage greater overall use. If agents become much cheaper to operate, organisations may respond by deploying more of them, running them for longer, or applying them to tasks that were previously uneconomic. Efficiency can reduce the compute required for an individual task while still increasing total demand.
That increased demand meets infrastructure that cannot expand as quickly. Models and software can improve quickly, but grids, substations, transformers and power-generation infrastructure usually have much longer development cycles. The IEA notes that while a data centre can sometimes be developed within two or three years, the broader energy infrastructure required to support it often involves longer planning and construction periods. Where grid capacity is constrained, each available megawatt becomes a more valuable production resource. The amount of power available remains important, but so does the amount of useful computation that can be produced within that power envelope.
That changes how we should understand capacity. Improvements in accelerator performance, model architecture, workload scheduling, caching, utilisation and inference software can increase computational output without increasing a site’s electrical connection. OpenAI’s recently reported Jalapeño inference hardware illustrates the direction of travel: the company says the chip can deliver more AI work per unit of power while increasing throughput and reducing latency. Efficiency can therefore act as a form of virtual capacity. If two operators each control 100 MW, but one can consistently deliver substantially more useful AI work within that power envelope, their nominal capacity may be identical while their productive capacity is not.
The same constraint applies to physical space and cooling. AI systems are concentrating more computational power into individual racks, increasing both power density and heat output. Packing more accelerators into the same building only creates useful capacity if the electrical and thermal infrastructure can support them. This is one reason liquid cooling is moving from a specialist technology towards a more central part of AI data-centre design. Microsoft, for example, has introduced a closed-loop chip-level cooling architecture that it says eliminates evaporative water consumption for cooling and could avoid more than 125 million litres of water annually per data centre. The example also shows why power, cooling, water use and rack density cannot be treated independently.
The same shift creates a measurement problem. Power Usage Effectiveness, or PUE, has been valuable for showing how much facility energy is required beyond the electricity IT equipment consumes. It does not, however, measure whether that IT equipment is producing useful work efficiently. Uptime Institute’s 2025 survey placed average PUE at around 1.54 and noted that the headline industry figure had changed little for six years. Uptime has consequently argued for productivity measures that relate computational work to energy consumption. For AI inference, tokens per kilowatt-hour might offer one operational measure. Still, even that is incomplete: an efficient model that solves a task in 1,000 tokens may be more valuable than one generating 10,000. A more useful long-term measure may therefore be useful AI work per unit of energy, water and infrastructure.
Capacity will remain essential. The AI industry will continue to build larger data centres, secure new power supplies and deploy large quantities of computing hardware. As agentic systems create more persistent inference demand and physical resources become harder to expand, however, efficiency may increasingly determine the productive value of that capacity. Operators that can support more useful computation within the same power, cooling, water, and space constraints can accommodate more workloads without waiting for equivalent growth in physical infrastructure.
For AI infrastructure, installed megawatts will remain a headline measure. The more consequential measure may increasingly be how much useful AI work those megawatts can support.
Above the City with CRANK at Level 43
Building the Infrastructure Behind the UAE’s AI Ambitions
Holcim Appoints Rozhgar Barzan as CEO for UAE and Oman


-
 Trending1 year ago
OPPO A6 Pro 5G Review: Reliable Daily Driver
-

 Tech News2 years ago
Denodo Bolsters Executive Team by Hiring Christophe Culine as its Chief Revenue Officer
-
 VAR2 years ago
Microsoft Launches New Surface Copilot+ PCs for Business
-
 Automotive2 years ago
AGMC Launches the RIDDARA RD6 High Performance Fully Electric 4×4 Pickup
-
Tech Interviews3 years ago
Navigating the Cybersecurity Landscape in Hybrid Work Environments
-

 Hospitality2 years ago
Gulfood 2025 30th Edition Kicks Off Today, Setting New Benchmarks in F&B Growth and Innovation
-
 VAR11 months ago
Huawei Nova 14 Pro Review: Where Camera Excellence Meets Ecosystem Evolution
-

 Tech News1 year ago
Nothing Launches flagship Nothing Phone (3) and Headphone (1) in theme with the Iconic Museum of the Future in Dubai